
Keep Confidential Data Private in AI Benchmark
How to deploy public benchmarks on protected data?
AI competitions and benchmarks are extremely effective ways of crowdsourcing science and solving complex problems. However, giving public access to data is absolutely out of the question in certain application domains where the data are sensitive, typically in medicine, but also in areas such as finance, defense, or education.
Today, I'll show you how to organize impactful benchmarks or competitions on protected data, depending on how strict your constraints are. We'll start with the simplest solution, code submission, which is often enough. Then we'll see what to do when the data must not leave your own servers: connecting your own compute workers, deploying your own instance of the platform, or using synthetic data. All examples are based on the platform Codabench.
Hiding the data with code submission
In a benchmark, participants do not need to access the data to be evaluated on it. With code submission, participants send their algorithm instead of their predictions. The platform runs it on the hidden data, and only returns scores and logs. The data is never shown to participants. (I compare the two formats in more detail in this post.)
On Codabench, this is a standard setup: the organizers upload the data with the competition bundle, and write an ingestion program that loads the participants' code and runs it on the data. You decide what goes back to participants: scores, logs, plots. Just make sure that nothing in this output leaks the data itself, such as a submission printing its inputs into the logs.
- ✅ Participants can't access the data
- ✅ Working on the real data
- ✅ Simple to set up
- ❌ The data is stored on the platform's servers
For many datasets that cannot be made public, this is already sufficient. But sometimes it is not: your data may be under a strict agreement, or your security team may simply not accept that it is stored on a third-party server. In this case, there are other options.
When the data must stay on your servers
Option 1 – Connect your own compute workers
Codabench lets organizers connect their own computing resources (either on premise or cloud computing) to their benchmark. These compute workers receive participants' submissions, run them, and send back the results.
The trick is to store the data directly inside your machines instead of uploading it to the platform. The evaluation program is fully customizable and can read the data in the way you decide. This way, the data never transits through Codabench, nobody can access it, and the benchmark can still be hosted on Codabench's public server, with its visibility and its community. You control the output scores, logs and plots participants receive to evaluate their solutions and populate the leaderboard.
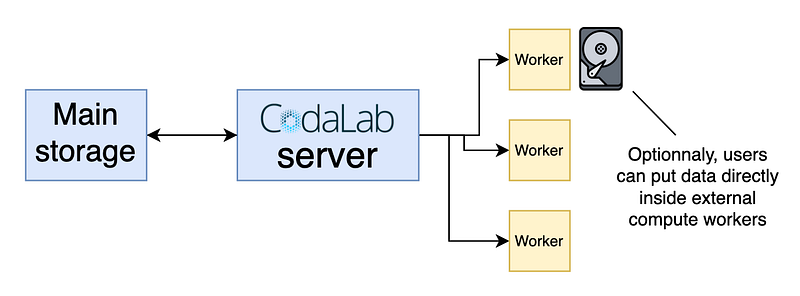
This protocol was validated by Dassault-Aviation security engineers. Concrete implementation details are given in Codabench's documentation.
- ✅ Data never leaves your machines
- ✅ Benchmark stays on the public platform
- ❌ You need to provide and maintain the computing resources
Option 2 – Deploy your own instance of the platform
Codabench is open source, so you can also deploy your own instance of the whole platform, on your own infrastructure. Everything is then under your control: data, submissions, user accounts, leaderboards. The instance can even run on an internal network, for benchmarks that are only open to selected participants.
This is more work: you need to install the platform, keep it up to date, secure it and host it. Your benchmark also loses the visibility of the public server, as participants have to create an account on your instance. This option makes sense for organizations that plan to run many benchmarks, or that cannot rely on any external service at all.
- ✅ Full control over the whole platform
- ❌ Installation and maintenance effort
- ❌ Less visibility
Option 3 – Use synthetic data
A different approach is to generate a synthetic version of the dataset. This means training a generative model to mimic the data, and creating a fake version of it, typically with non-existent patients or users. This fake dataset can then be shared freely.
The problem with this approach is that it relies on the generation methodology, makes it difficult to guarantee true privacy, and forces participants to study artificial data that may behave differently from real data.
- ✅ Can share the dataset with participants
- ❌ Tricky to have security guarantees
- ❌ Not working on the real data
Recommendation
Whenever possible, evaluate the algorithms blindly, with code submission, on the real data: on the public server if storing the data there is acceptable, with your own compute workers if it is not, or on your own instance if you need full control.
Synthetic data is best used as a complement. In order to help participants dive into the challenge, and have data at hand to develop their solutions, organizers can use generative models to create and share a sample dataset. This way, participants have a clear idea of the dataset form, while the final evaluation is performed on the true dataset, kept hidden.
Conclusion
Evaluating AI models on sensitive data is crucial across many application domains. In many cases, code submission alone is enough to keep the data away from participants. When the data must not leave your servers, you can connect your own compute workers to the public platform, or deploy your own instance of Codabench. Synthetic data, finally, is a useful complement to let participants develop their solutions.
By enabling privacy-preserving evaluations while maintaining scientific rigor, such platforms make it possible to turn protected datasets into public benchmarks. This greatly accelerates research progress, and helps bridge the gap between real-world applications and open science.