
ML Challenges: result submission VS code submission

When you organize a machine learning challenge, one of the first design decisions is what participants actually send you. Either they upload the predictions of their model, or they upload the model itself and you run it. Platforms such as Kaggle, CodaLab Competitions, EvalAI or Codabench support both, and both are widely used. Each format has its place, and the right choice depends on what you expect from your challenge.
In this post, we'll look at what each format makes possible, what it costs, and how to pick the right one. If you are in a hurry, a table at the end of the post sums it all up.
Two ways of submitting
The main difference between the two formats is where the model is executed.
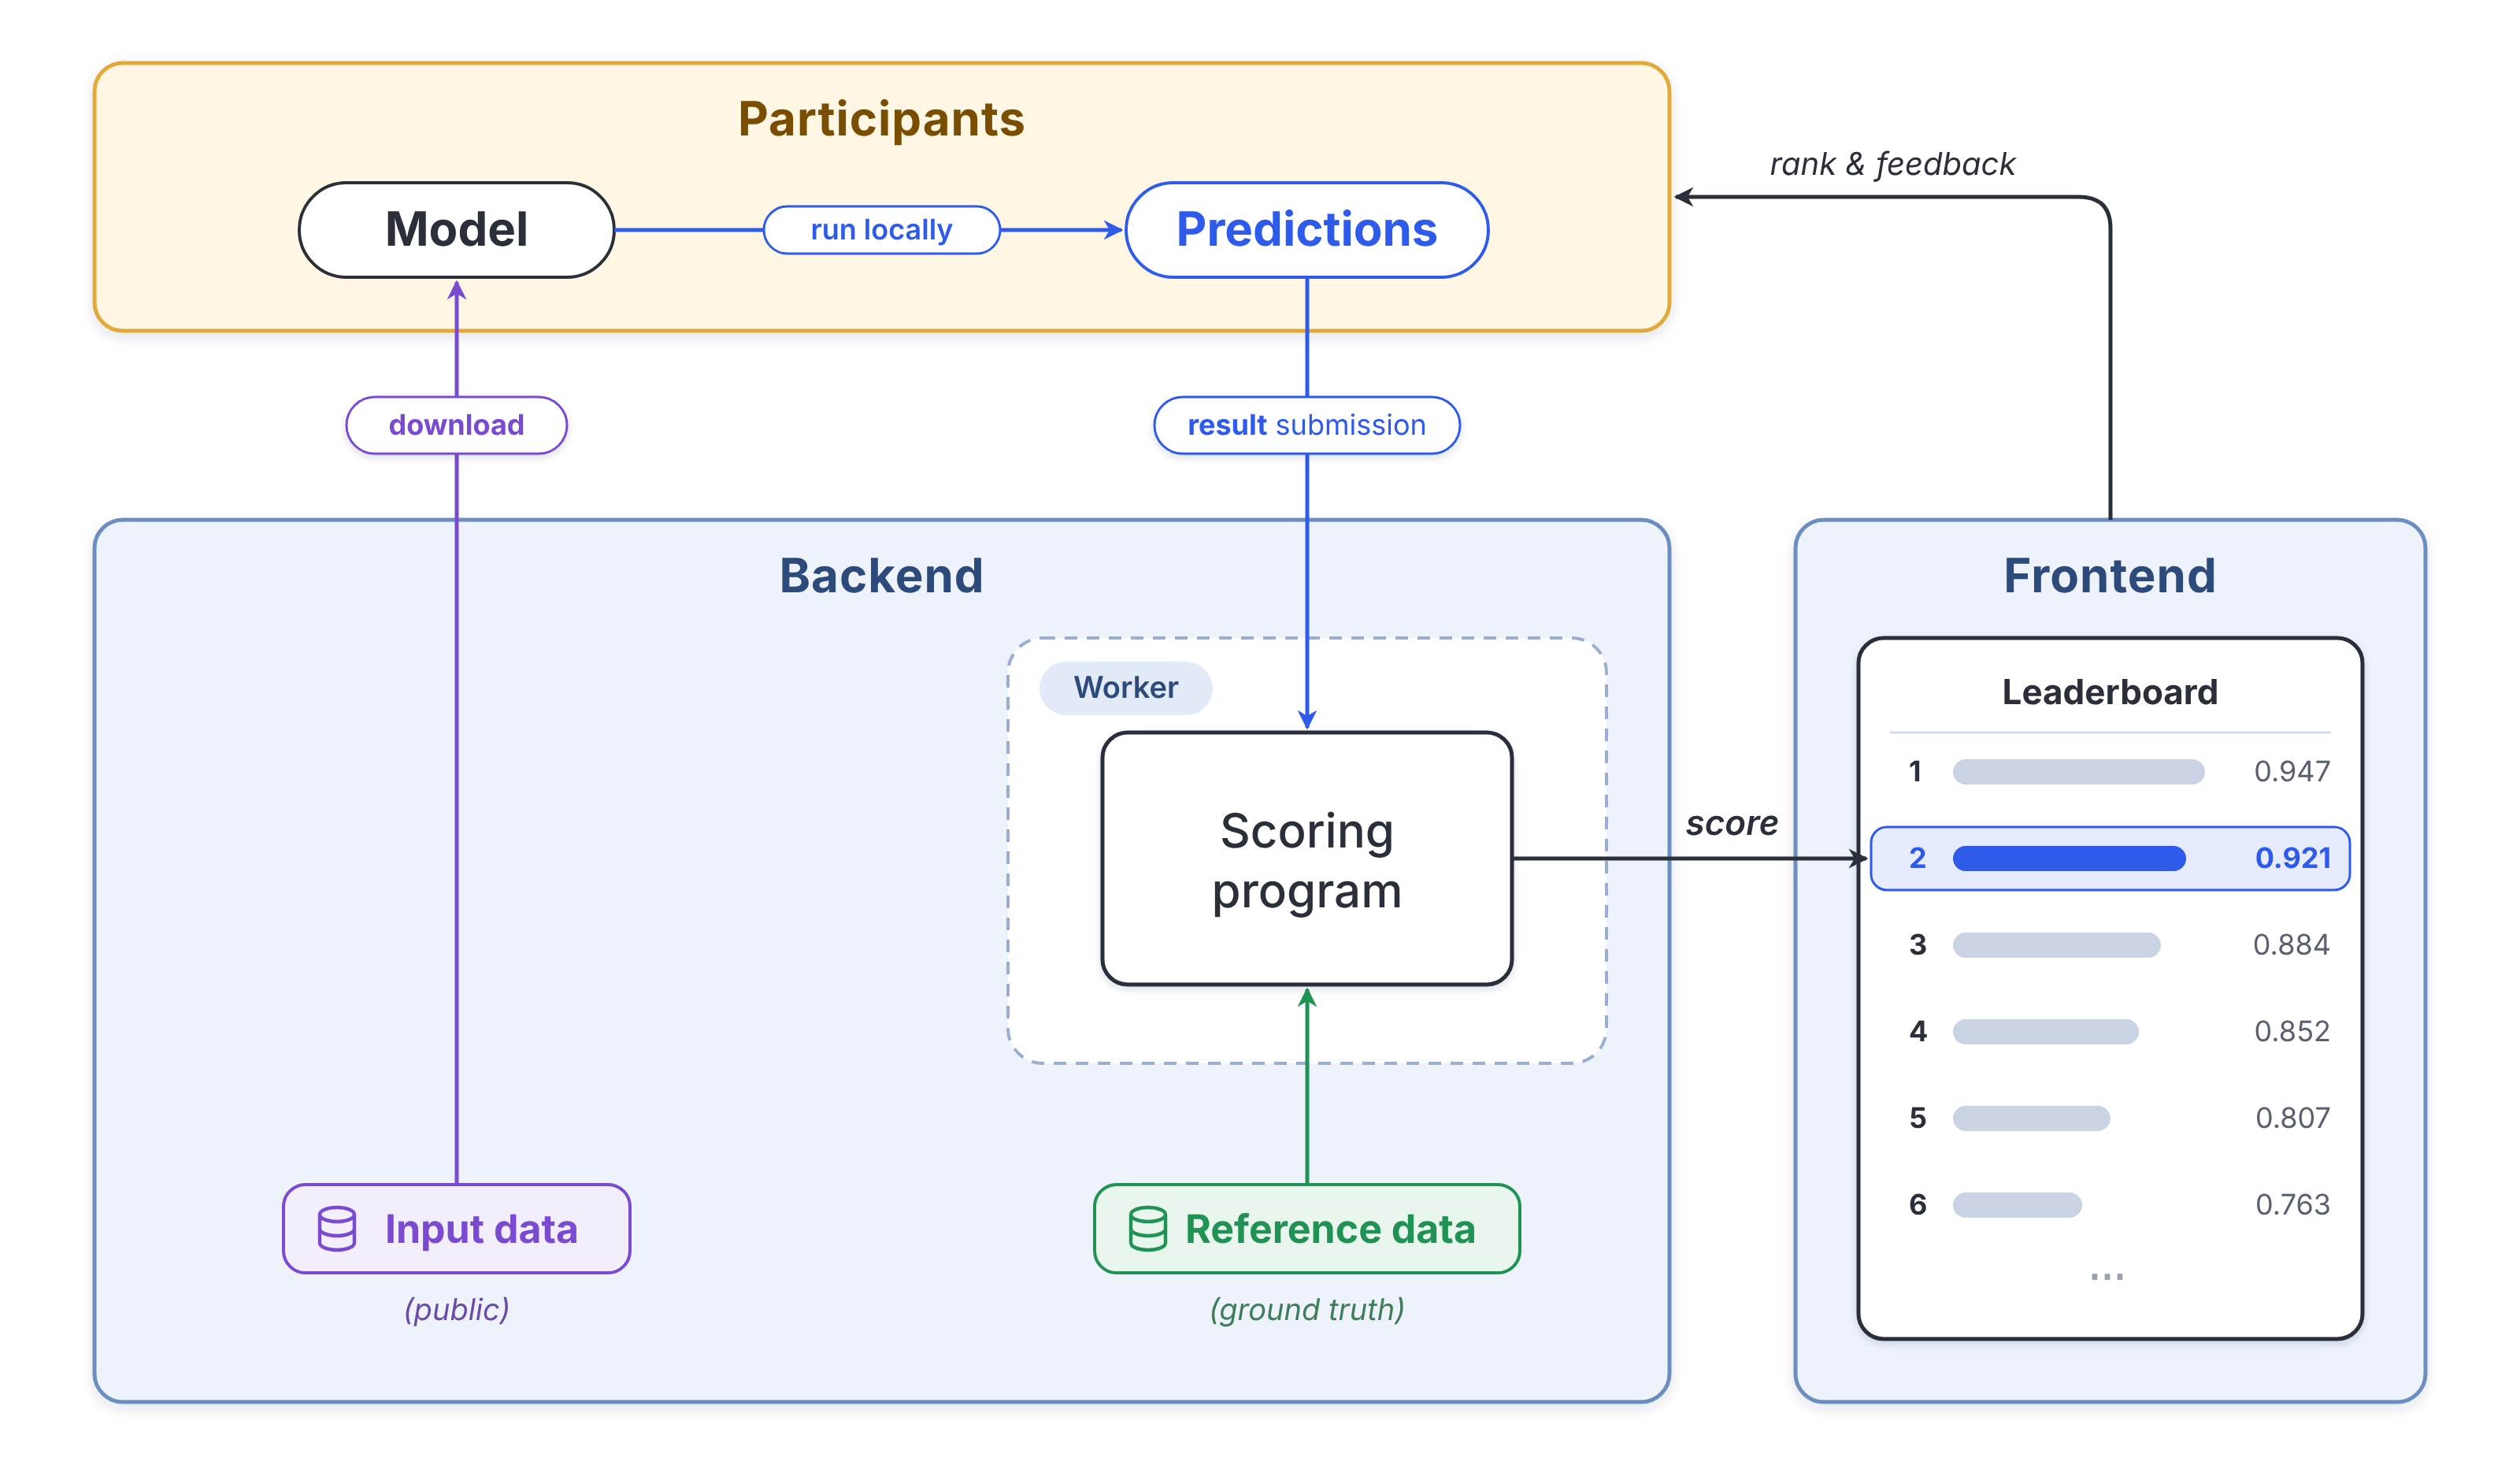
With result submission, the organizers release the test inputs but keep the labels. Participants run their model on their own machines and upload a file of predictions, typically a CSV.
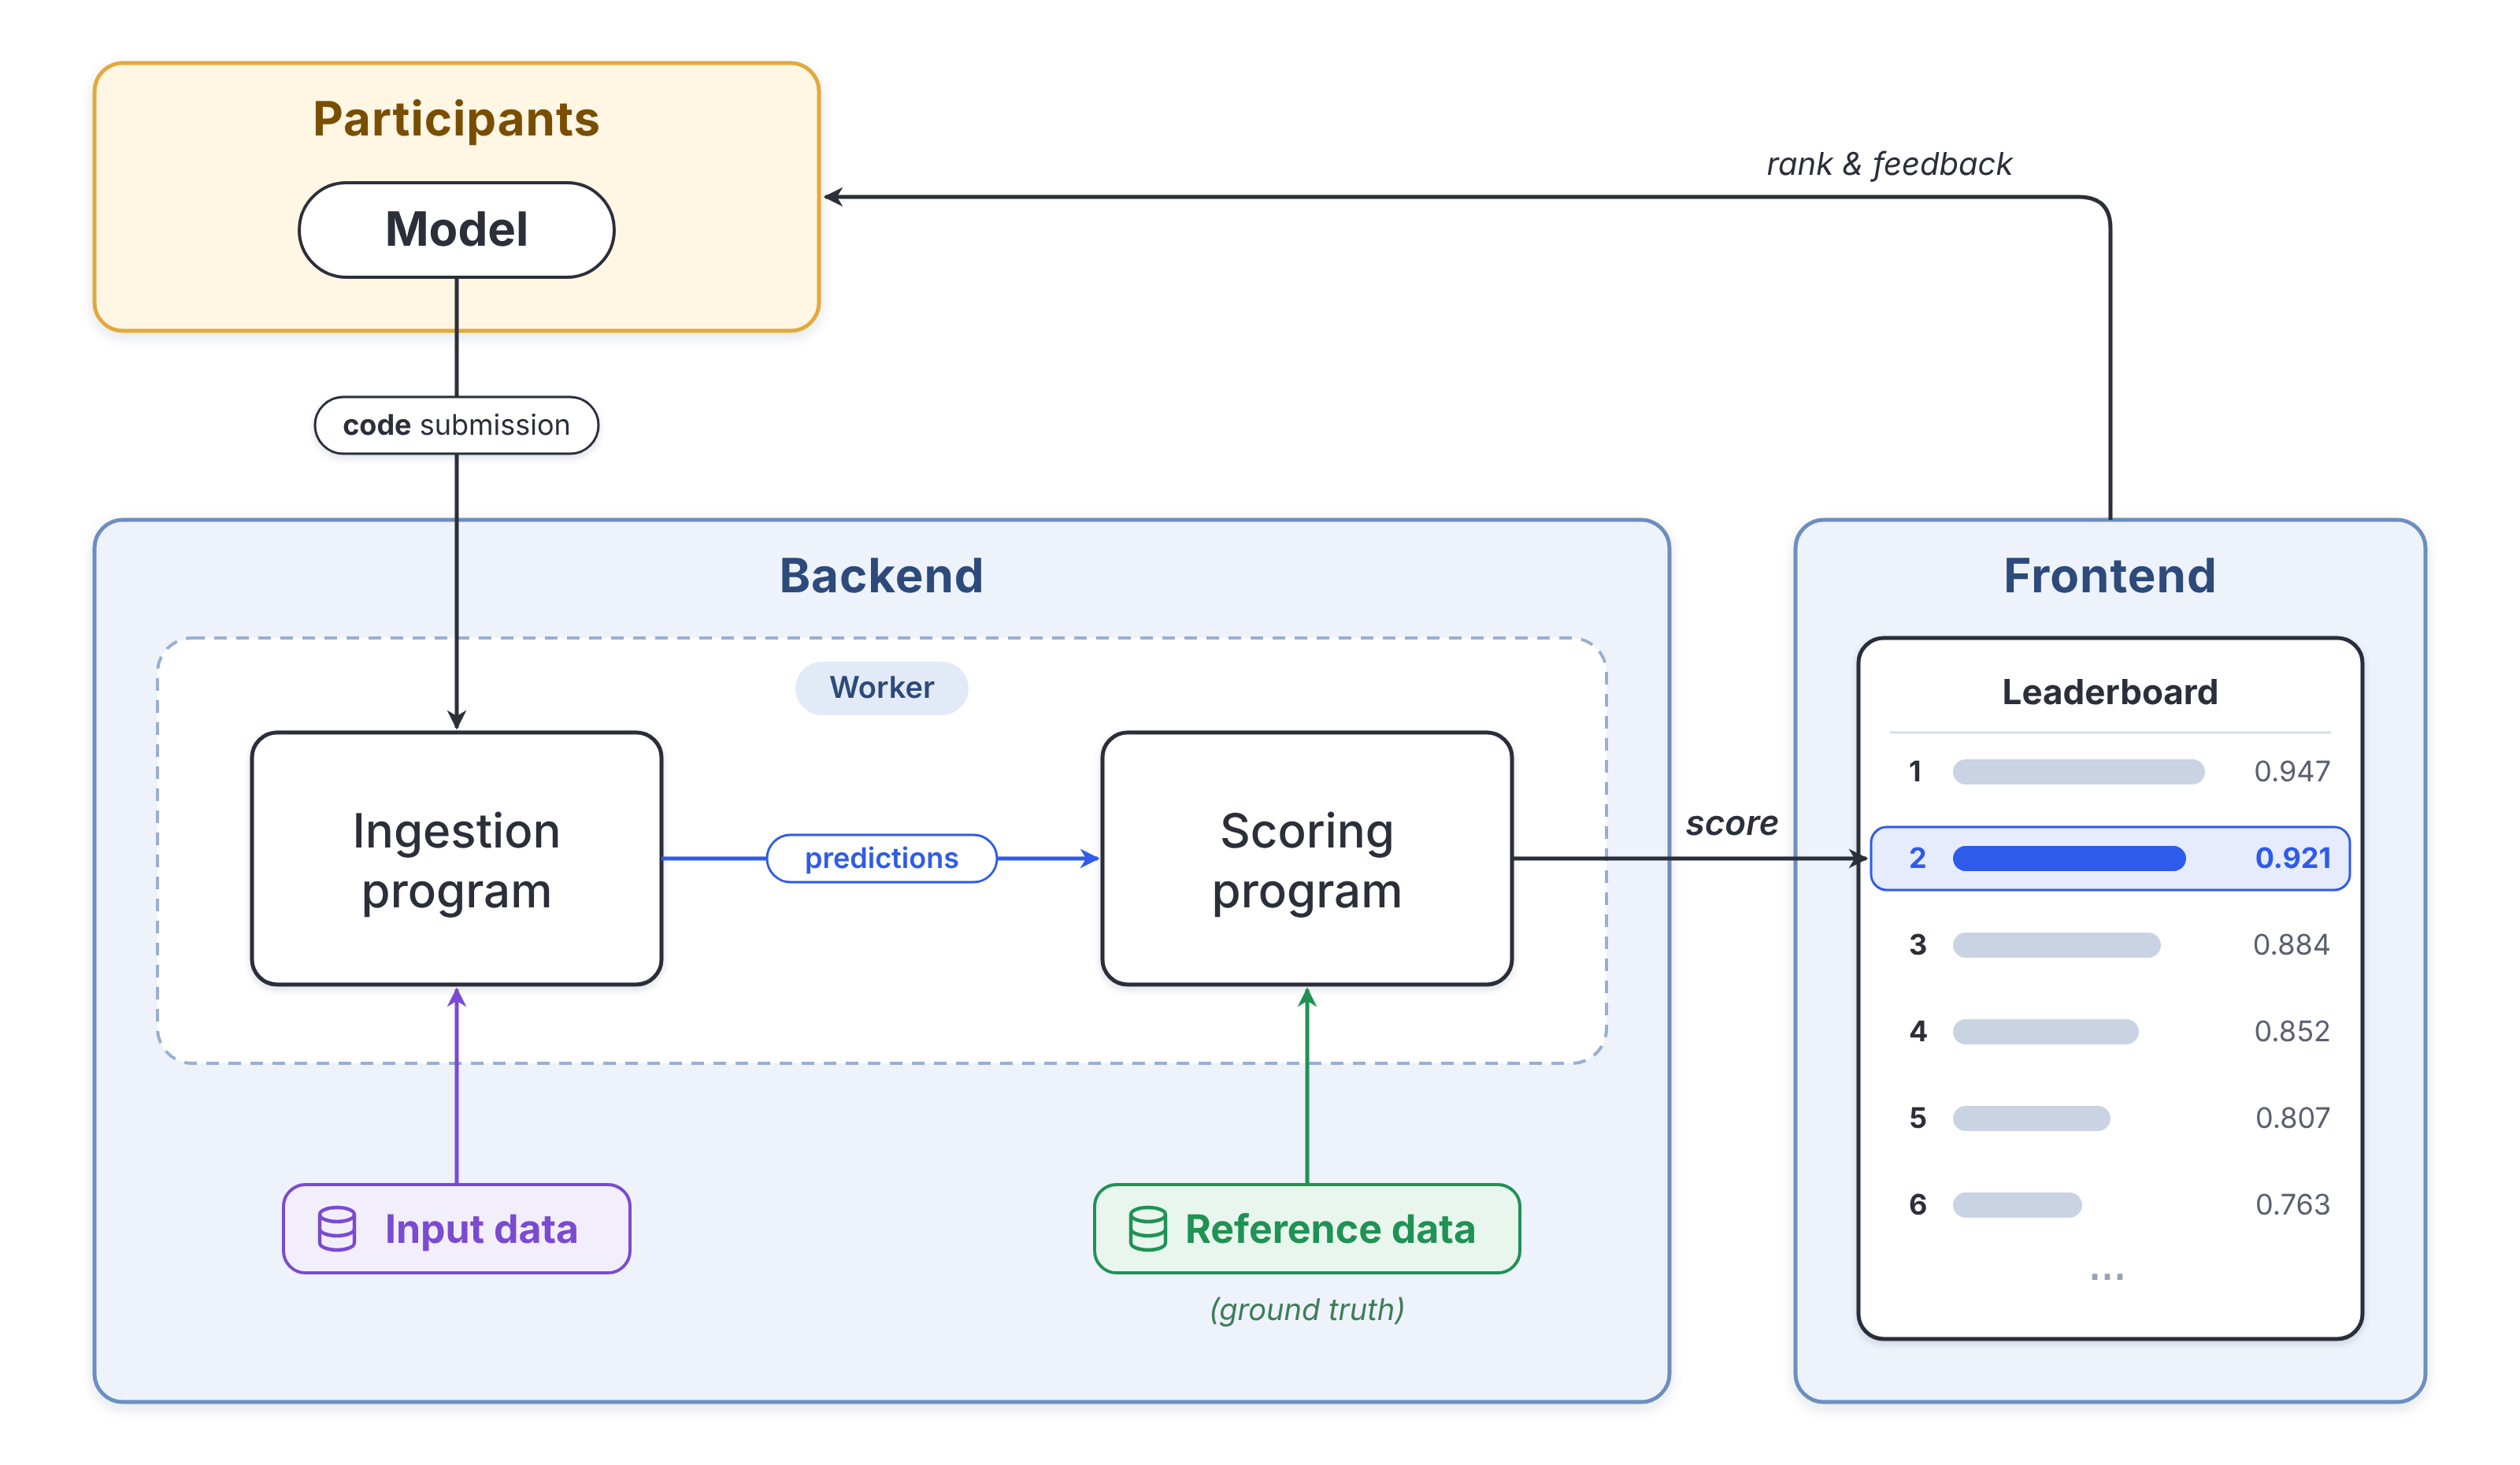
With code submission, participants upload a program and the platform runs it on the organizer's infrastructure. It can be a trained model that is only used for inference (this is what people often call model submission), or the full pipeline including training, as in AutoML challenges. In settings such as reinforcement learning, the submission is an agent that interacts with an environment, like the power grid controllers of the L2RPN challenges.
The case for result submission
Result submission is the historical format, and it remains the default on many platforms for good reasons.
Low barrier to entry. Participants can use any language, any library, any hardware, and as much of it as they like. There is no environment to match, no time limit, no cryptic error in a remote log file. You download the data, you work, you upload a CSV. This matters if you want a large and diverse community, including students and newcomers.
Cheap for the organizers. Scoring a prediction file costs almost nothing. A challenge with thousands of participants can run on a small server, because the heavy computation is spread over the participants' machines.
Fast feedback. Submissions are scored in seconds, so participants can iterate quickly.
No ceiling on model size. If the best solution needs a cluster of GPUs or a model with hundreds of billions of parameters, participants can use it. With code submission, the organizer's hardware sets the limit.
Participants keep their code. Some teams, especially from industry, cannot upload their code to a third-party server. Result submission lets them compete anyway.
Sometimes the predictions are the goal. If you want the best possible labels for a dataset, or forecasts of events that have not happened yet (as in the M forecasting competitions), the predictions themselves are the deliverable. In forecasting, the problem of releasing the test inputs mostly disappears, since the ground truth does not exist yet at submission time.
The weaknesses discussed below also have well-known mitigations: limiting the number of submissions per day, splitting the test set into a public and a private leaderboard, adding unscored decoy samples to the test set to make hand-labeling impractical, or asking the top-ranked teams to send their code for verification before awarding prizes, as many Kaggle competitions do.
What you can do with the code at hand
With result submission, the organizer receives a file of numbers. With code submission, the organizer receives the method itself, and this opens the door to many experiments.
Reproducibility
With a prediction file, you know what participants say they did. You can ask them for a fact sheet describing their method, but you have to trust that it is accurate and complete, and specific enough for someone else to obtain the same results. In practice, it rarely is.
With the code, you run it and you see. Even when only inference is submitted, the predictions are produced on the platform by a model you hold: anyone can run it again and get the same outputs, and the score on the leaderboard is attached to an actual artifact, not to a description of it. When training is part of the submission, you go one step further and reproduce the whole method from scratch. This is the basic requirement of experimental science: being able to re-run what you compare.
Control cheating
With result submission, nothing tells you how the predictions were obtained. They could come from a forbidden external dataset, from a model that has already seen the test set, or simply be corrected by hand by a motivated human.
With code submission, the test inputs are not available to participants, so hand-labeling is out of the question. And if a doubt remains, you can always read the code and check that it follows the rules of the challenge. Knowing that this is possible is already quite dissuasive.
Evaluate more than one number
A prediction file gives you one prediction per test sample. That is enough to compute a score and, with bootstrap over the test samples, some error bars. Not much more. When you hold the code, you can design the evaluation protocol you actually want:
- Several runs with different random seeds, to measure the variance due to training, and not only the variance due to the test sample.
- Cross-validation, or retraining on different splits, when training is part of the submission.
- Several hidden datasets. Methods can be evaluated on tasks they were never tuned for. In the AutoDL challenge, for instance, the final phase was run on datasets that participants never saw. This is the best protection I know against overfitting a single benchmark.
- New data, after the challenge. Data collected months or years later can be used to re-evaluate every submission. The challenge becomes a collection of runnable methods instead of a frozen leaderboard.
- Learning curves. You can train on 10%, 50% and 100% of the data, or score the model at regular time intervals during training, and look at how fast it learns, not only where it ends up.
- Robustness tests. Noisy, corrupted or shifted inputs, missing features, adversarial perturbations: tests you cannot ask participants to run on their own without telling them what is coming.
Fairness and compute measurement
This point has become very important in recent years. When predictions arrive as a CSV, you have no idea how they were produced. Maybe by a small model on a laptop in ten minutes. Maybe by an ensemble of fifty large models running for a week in a data center. Both get the same kind of line on the leaderboard.
With code submission, every submission runs on the same hardware, in the same environment, under the same limits. Training time, inference time, memory, and even energy consumption can be measured in a comparable way and reported next to the score (see my post on exotic metrics). You can also make the budget a rule of the game, for example "20 minutes on one GPU". Efficiency then becomes part of the problem, and a clever small model can beat a brute-force one.
Given the size of today's models, I find this one of the strongest arguments for code submission. It is the only way to compare methods on a level playing field. It is also fairer to participants: a student with a laptop and a large lab get exactly the same machine, and the same time to use it. Of course, some will see the total freedom of result submission as an advantage, since you can throw all the resources you have at the problem. But then the leaderboard partly ranks resources, not only ideas.
Keep the test data hidden
With result submission, the test inputs must be given to participants, otherwise they cannot predict anything. This has consequences: participants can look at them, use them for semi-supervised learning or test-time adaptation, or even label some of them by hand. In a sense, the test set is partially consumed by the challenge.
With code submission, the test inputs never leave the organizer's servers. The same test set can be reused for longer, and it becomes possible to evaluate models on confidential data, such as medical records, that could never be released publicly (more on this in this post).
Build on the results
At the end of a code submission challenge, the organizers hold a set of working, comparable implementations. They can be studied side by side, combined, re-run as baselines for the next edition, or released as references with the authors' agreement. With result submission, what remains after the challenge is a ranking, plus whatever the participants decide to publish.
The price: code submission is harder to organize
On the platform side, setting up code submission is not very complicated (on Codabench, it is mostly a matter of writing an ingestion program that loads and runs the participant's code). But running other people's code on your machines brings real work.
The software environment. Submissions run inside a container, typically with Docker or Podman on Codabench, and the organizers choose the image. Every library that participants need must be in it, in a compatible version. You have to anticipate: which deep learning frameworks, which CUDA version, which library that became popular last month. When something is missing, the participant gets an ImportError instead of a score. Good practices are to publish the image, to provide a starting kit that runs locally in the same image, and to update the image during the challenge when reasonable requests come in.
Computing resources. This is the main cost. The computation that was spread over participants' machines is now on yours. A quick estimate: 200 teams, 5 submissions per day each, 30 minutes of GPU per submission, that is 500 GPU-hours per day. You will need time limits, daily quotas, a queue, and the acceptance that everybody submits during the last days. On Codabench, organizers can connect their own compute workers to their competition, on premise or in the cloud, to absorb this load.
Security. You are executing untrusted code. Workers should run with limited permissions and, ideally, without network access, otherwise the hidden data will not stay hidden for long. Be careful with what is sent back to participants too: if logs are shown in full, a submission can simply print the test inputs.
A harder life for participants. Debugging a remote run through logs is less comfortable than working locally, and submissions may take minutes or hours to be scored. Expect more questions on the forum.
None of this is a blocker, and many challenges run with code submission every year. But it is a real investment that must be planned before launching.
Summary
| Result submission | Model submission (inference only) | Full code submission | |
|---|---|---|---|
| Low barrier for participants | ✅ | ⚠️ | ⚠️ |
| Low compute cost for organizers | ✅ | ⚠️ | ❌ |
| Easy to set up | ✅ | ⚠️ | ⚠️ |
| No limit on model size | ✅ | ❌ | ❌ |
| Reproducible predictions | ❌ | ✅ | ✅ |
| Reproducible training | ❌ | ❌ | ✅ |
| Cheating control | ❌ | ⚠️ | ✅ |
| Test inputs stay hidden | ❌ | ✅ | ✅ |
| Advanced protocols (seeds, CV, new datasets) | ❌ | ⚠️ | ✅ |
| Equal resources and comparable compute | ❌ | ⚠️ | ✅ |
| Evaluation on confidential data | ❌ | ✅ | ✅ |
So, which one should you choose?
It depends on what the challenge is for.
- Result submission fits when you want many participants quickly, have a small budget, need to allow very large models, or when the predictions themselves are what you are after. Use a private leaderboard and ask the winners for their code.
- Code submission fits when you want a scientific benchmark: reproducible results, comparable methods, measured efficiency, generalization to new data, or data that cannot be released. Include training in the submission if the learning procedure is what you study (AutoML, few-shot learning, ...), and inference only otherwise.
- Both, in sequence. A possible design is a development phase with result submissions on a validation set, so that participants iterate quickly, followed by a final phase with code submission on hidden data, so that the final ranking is reproducible and computed on the same hardware for everyone. Codabench lets you configure each phase differently.
Personally, since the goal of most of the benchmarks I organize is to learn something about methods, I go for code submission whenever the resources allow it. It costs more, but at the end you have methods you can actually run, compare and re-evaluate. With great power comes great responsibility, and a larger compute bill.